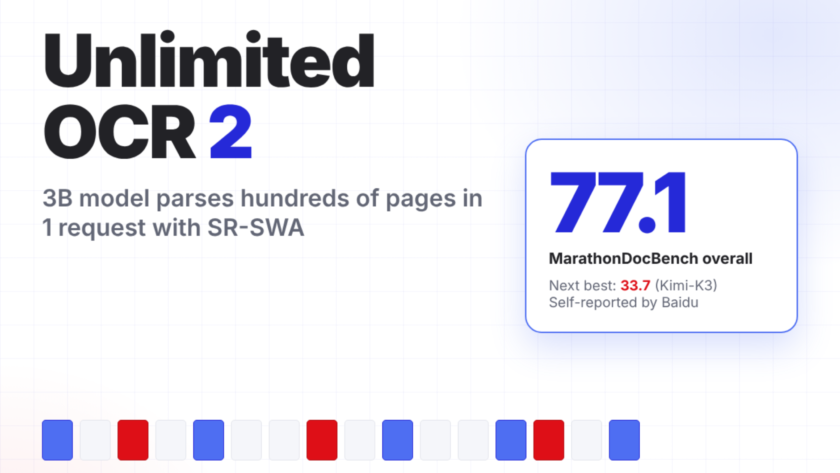
Baidu has released Unlimited OCR 2, an open-source OCR model built for very long documents. The 3B model parses books, filings and reports of hundreds of pages in one request. Its core change is SR-SWA, a sparse attention scheme that keeps per-step decoding cost nearly flat. Weights ship under the MIT license, with code on…
In this tutorial, we implement OmniParseBench, Datalab’s open benchmark for document parsers, which grades a parser’s output with 16,288 small pass-or-fail tests across 2,937 pages, from scanned forms and handwriting to arXiv math and dense tables. Rather than trust the leaderboard, we rebuild it from the verdicts Datalab released for 27 parsers, after feeding the…
Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage…
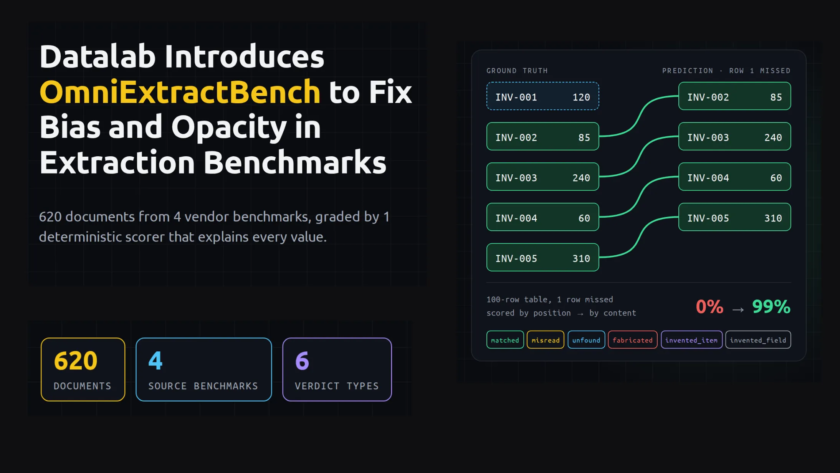
Datalab has released OmniExtractBench, an open benchmark for structured document extraction. It tests how accurately a system fills a JSON schema from a PDF. The benchmark pools 620 documents from 4 existing benchmarks. One deterministic scorer grades all of them and explains each decision.
The release lands while extraction vendors publish their own leaderboards. Datalab…
Alibaba’s Qwen team has released Qwen-Image-2.1, a unified text-to-image generation and image editing model. Its visual generation component has 7B parameters across 32 single-stream DiT layers. One checkpoint covers text-to-image, multi-reference editing, local edits, and transparent RGBA output.
Is it deployable? Yes, for research and evaluation. Day 0 support covers Diffusers, ComfyUI, vLLM-Omni, SGLang,…
AI weather models have spent three years closing the gap with physics-based forecasting, but two problems stayed open: resolution too coarse for local terrain, and initialization tied to numerical weather prediction (NWP) analysis that arrives about six hours late. WeatherNext 3, released by Google DeepMind and Google Research, attacks both. It takes a live global…
Google DeepMind has released AlphaGenome Atlas, a catalogue of precomputed predictions for the molecular effects of every possible single-nucleotide variant in the human genome. That is roughly 9 billion single-letter changes. The release also introduces the AlphaGenome Variant Impact (AVI) score, a single number that ranks variants by predicted impact, plus per-variant feature attributions and…
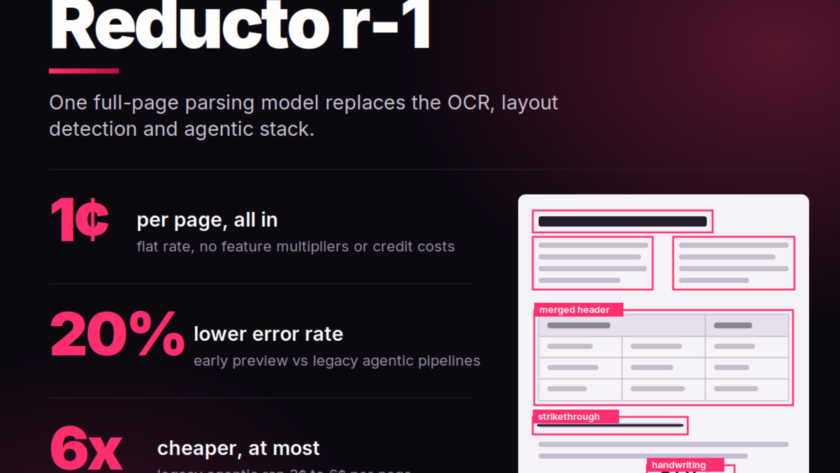
Last week, Reducto announced r-1. It is the first model in a new parsing family built on a rewritten architecture, and it replaces the company’s multi stage agentic OCR with one full page pass. Reducto says r-1 is more accurate than its most powerful legacy agentic models, faster, and up to 6x cheaper.
Is…
Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in…
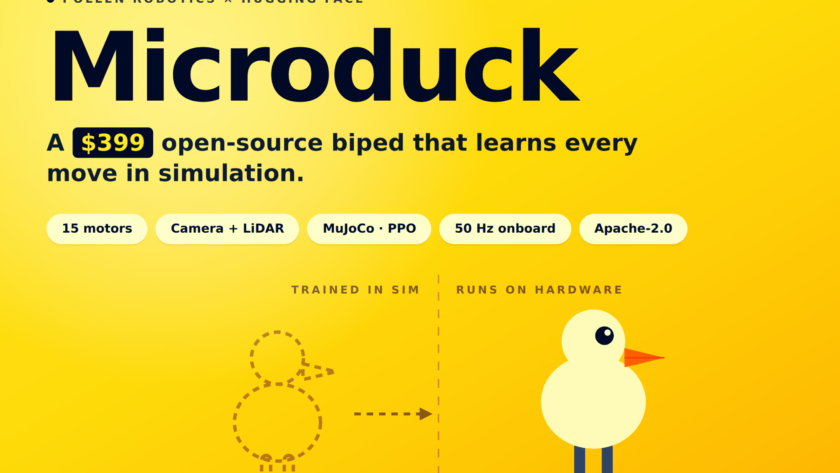
Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You Train with Reinforcement Learning
Most robotics launches ask you to trust a demo video. Pollen Robotics, the Bordeaux robotics team at Hugging Face, is instead shipping the training loop. This week it opened pre-orders for Microduck, a 25 cm bipedal robot in which every movement — walking, sitting, kicking, roller-skating, standing back up after a fall — is a…