Cohere has released Parse (parse-v5.0), a document parsing model aimed at high-volume enterprise ingestion. It is a 2.3B-parameter vision language model with an 8,192-token context window and a ~4.6GB footprint, built on Cohere Labs’ North-Micro-Vision-Instruct architecture. Parse takes a PDF, PPT or JPEG page as a base64-encoded data URI and returns Markdown containing text in…
Defenders wanting to use advanced AI have faced a difficult dilemma: adopt enormous frontier models that could be expensive to deploy and difficult to control across enterprise codebases, or turn to smaller open-weight models that might struggle with complex vulnerability remediation and require teams to build their own tooling and infrastructure from scratch. Until now.…
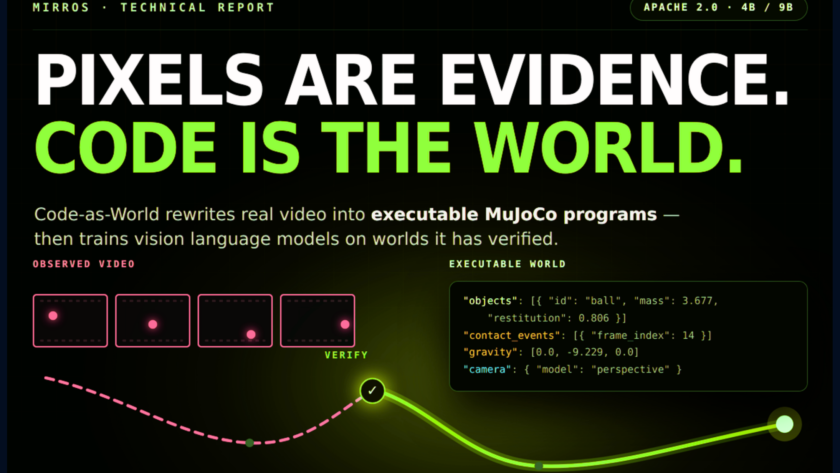
MirroS released Code-as-World: a paradigm that represents physical worlds through executable world representations. The argument is narrow and testable: pixels are evidence of a physical scene, not its ontology. A video model can predict plausible frames without ever representing mass, contact, or gravity. So instead of pixels, latents, or captions, Code-as-World represents a scene as…
Introduction
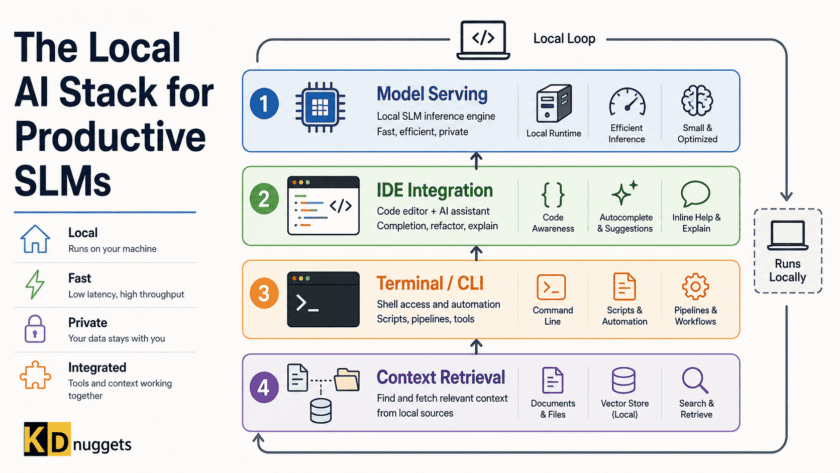
Running a small language model locally is straightforward. Running one productively — inside a real development workflow, with proper context, tool access, and iteration speed — is a different problem entirely.
The gap between "I got a model responding in my terminal" and "I have a local AI setup that actually improves how I…
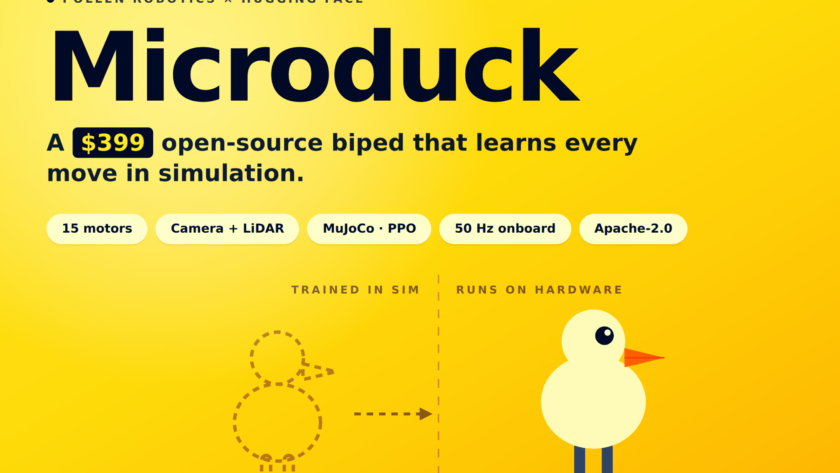
Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You Train with Reinforcement Learning
Most robotics launches ask you to trust a demo video. Pollen Robotics, the Bordeaux robotics team at Hugging Face, is instead shipping the training loop. This week it opened pre-orders for Microduck, a 25 cm bipedal robot in which every movement — walking, sitting, kicking, roller-skating, standing back up after a fall — is a…
Today, we’re introducing Gemini Omni 1.1 Flash, a new suite of creative controls and generative video capabilities to support developers. Gemini Omni brought real-world reasoning to generative creation, and today’s updates make Omni 1.1 production-ready for professional use via the Gemini API in Google AI Studio. Whether you’re building generative video workflows, creative tools, or…
Every day, your organization produces a mountain of words. Support tickets, contracts, clinical notes, customer reviews, emails, call transcripts. Roughly 80% of all enterprise data exists as unstructured text like this — and until recently, almost none of it could be analyzed at scale. It just sat there. Natural Language Processing changed that. And in 2026, with large…
Muse Glimmer is gaining attention in the local AI community and is being compared with Qwen's 27B-class models. In many cases, it is performing better, especially for local coding and agentic workflows.
Meta looks strong in the open-model space, and with a few more iterations, models like this could start competing closely with proprietary systems.…
Object removal models have improved faster than the metrics used to judge them. Diffusion erasers now reconstruct shadows, reflections and occluded structure convincingly, yet PSNR, SSIM, LPIPS, ReMOVE and CFD frequently rank their outputs the wrong way. The root cause is structural: erasure is an ill-posed, one-to-many task, so no single ground truth exists to…
Today, we are introducing Gemma 4 12B, our latest model designed to bring agentic multimodal intelligence directly to laptops. Bridging the gap between our edge-friendly E4B and our more advanced 26B Mixture of Experts (MoE), Gemma 4 12B packages powerful capabilities inside a reduced memory footprint. It is also our first mid-sized model to feature…