Video world models can render convincing clips that still break physics. Butter spreads like paint. Balls pass through walls. A team from NVIDIA, MIT and the University of Oxford argues the fix can come from language itself, not from extra visual, latent or numerical signals.
Their framework, Physis-Lang, treats physical language as a shared, optimizable…
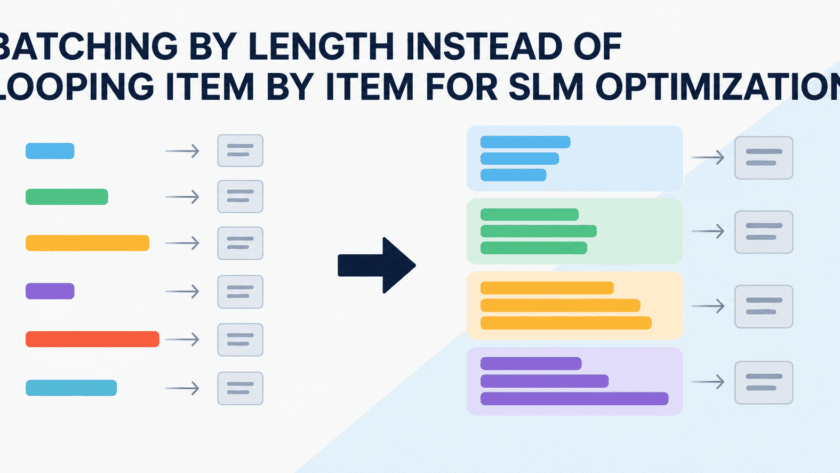
Previous articles in this series discussed constraining output space as well as reusing the prompt prefix with a key-value cache, both framed as approaches to small language model (SLM) narrow automation optimization. Let's finish this series off with the third entry, focused on batching by length instead of looping item by item.
As in our…
A Live Avatar to fit your brand needs Organizations often need distinct visual identities to fit their brand. In addition to a library of diverse, preset avatars, organizations can customize their Live Avatars. From a high-quality reference image, developers can generate a fully animated, responsive avatar while preserving reference likeness, brand styling, or character identity.…
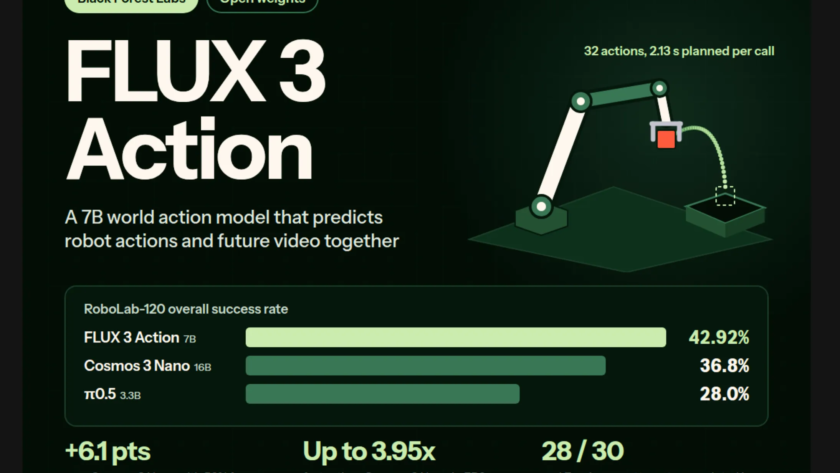
Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World Action Model That Tops RoboLab-120
Black Forest Labs (BFL), the lab behind the FLUX image models, has released FLUX 3 Action. It is a 7B open-weights World Action Model (WAM) for robot control. The model reads camera frames, robot state and a text instruction. It then predicts future video frames and the next chunk of actions together. On the RoboLab-120…
Introduction
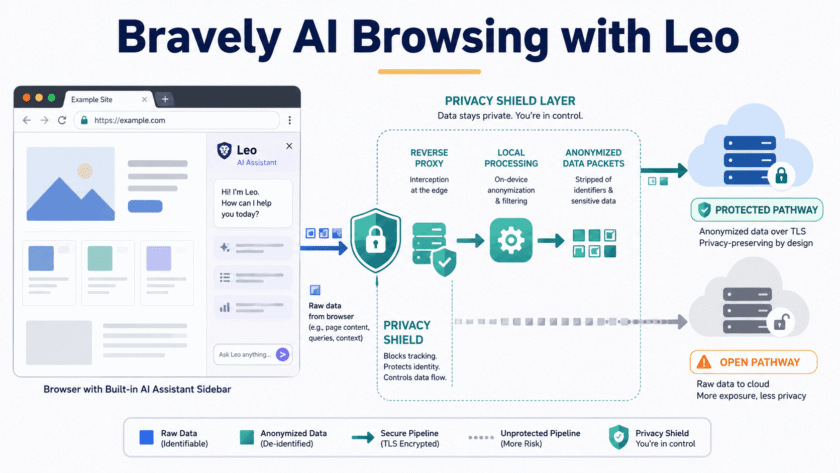
Data professionals live in their browsers. You're reading technical documentation, analyzing research papers, reviewing model cards, working through GitHub repositories, and summarizing industry reports — often all in the same afternoon. Increasingly, AI assistants sit alongside that work.
The tools most people reach for (Chrome with Gemini, Perplexity, ChatGPT in a pinned tab) are…
Alibaba’s Qwen team has released Qwen-Image-2.1, a unified text-to-image generation and image editing model. Its visual generation component has 7B parameters across 32 single-stream DiT layers. One checkpoint covers text-to-image, multi-reference editing, local edits, and transparent RGBA output.
Is it deployable? Yes, for research and evaluation. Day 0 support covers Diffusers, ComfyUI, vLLM-Omni, SGLang,…
Today, we’re launching agentic video understanding across our latest models: Gemini 3.7 Flash, 3.6 Flash and 3.5 Flash-Lite. This new capability improves accuracy while dramatically reducing token usage and costs for video analysis. Similar to agentic vision, which combines code execution with Gemini models’ native image understanding, agentic video understanding uses Gemini’s native video tools…
Robot developers do not have one compute problem. They have 3. A policy is trained on GB200 or H100 clusters, tested in Isaac Sim on RTX GPUs, then validated on a Jetson mounted inside a real robot. Each tier has its own cluster, its own scheduler, and its own glue scripts. NVIDIA OSMO is NVIDIA’s…
Sponsored Content
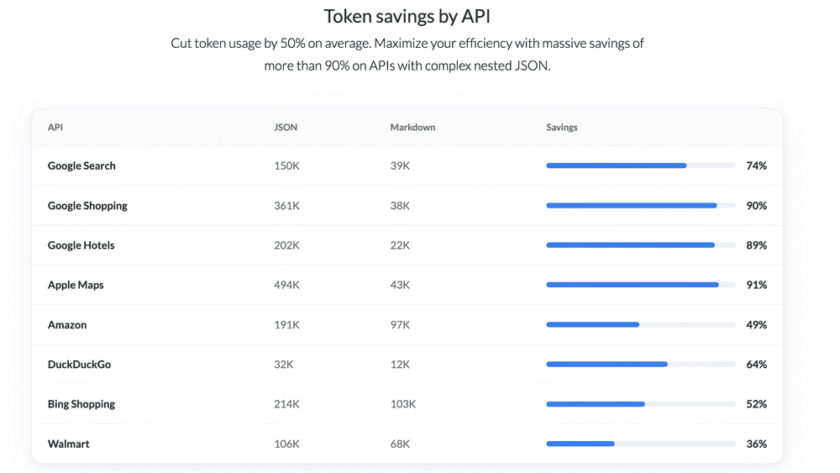
It's no secret that AI agents burn massive amounts of tokens on search results and file retrievals. They pull in dozens of full-length files, logs, and comment blocks, and just reading through those matches can consume tens of thousands of tokens, not to mention the recursive loops that lock…
AI weather models have spent three years closing the gap with physics-based forecasting, but two problems stayed open: resolution too coarse for local terrain, and initialization tied to numerical weather prediction (NWP) analysis that arrives about six hours late. WeatherNext 3, released by Google DeepMind and Google Research, attacks both. It takes a live global…